AI has a measurement problem.

I’m Jodi Casabianca — a psychometrician working on it!

I am a Research Scientist on the Applied Systems team at the Center for AI Standards and Innovation at the National Institute of Standards and Technology (NIST), where I work on advancing best practices for AI metrology. I am also the founder of BroadMetrics, a psychometric services and research firm. I write about measurement and AI evaluation on my Substack, Measuring AI.

I bring psychometrics — validity frameworks, reliability, item response theory — to AI evaluation, so that claims about AI systems rest on defensible evidence.

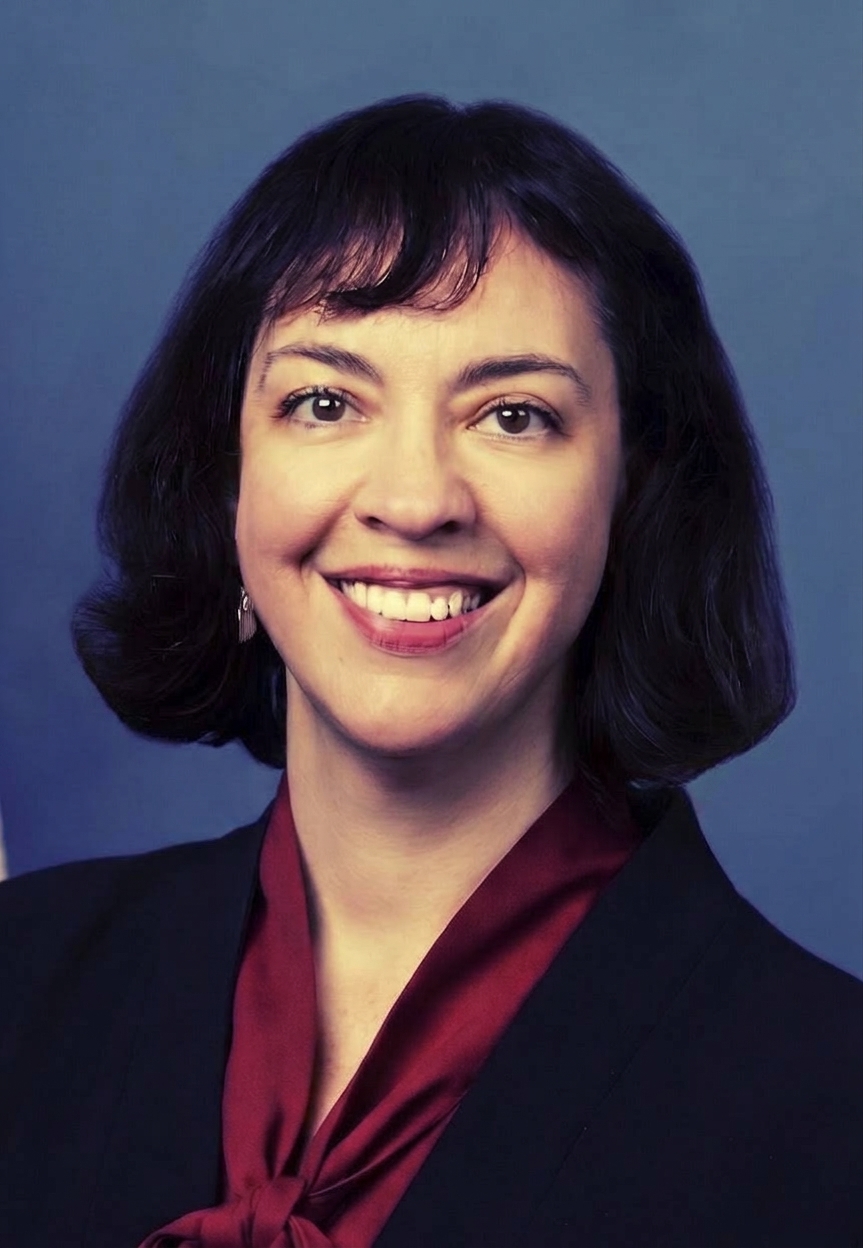
Portrait of Jodi M. Casabianca

News

Recent updates

About

Measurement science for the AI era

Benchmarks and leaderboards get plenty of attention, but most were not developed in a principled fashion — which leaves open the question of what they actually measure. The heart of my work is connecting AI measurement and psychometrics. Without a defined construct, a score is just another number — and when that number drives decisions with real-world consequences, the validity of those conclusions becomes a measurement question in its own right. I bridge psychometrics, AI, and real-world applications — from human rating systems and automated scoring evaluation to psychometric approaches for AI benchmarking. The methods are not all directly transferable, but those are the challenges that I'm currently enjoying.

I hold a Ph.D. in Psychometrics and Quantitative Psychology from Fordham University. My career spans research and faculty roles at ETS and the University of Texas at Austin, and a U.S. Department of Education–funded postdoctoral fellowship in advanced quantitative methods at Carnegie Mellon University and RAND.

Fun fact!

As a Ph.D. student at Princeton, my dissertation advisor Charlie Lewis helped edit Lord & Novick’s Statistical Theories of Mental Test Scores — the 1968 book that laid the foundations of modern test theory.

PsychometricsAI evaluationvalidity frameworksevidence-centered designraters & ratingsconstructed-response scoringscale developmentitem response theoryLLM benchmarking
Research

Building the measurement science AI evaluation needs

Psychometrics for AI Evaluation

Applying validity theory, evidence-centered design, and item response theory to AI benchmarking and evaluation pipelines. AI evaluation faces the same threats to validity that educational measurement solved decades ago — construct underrepresentation, score inflation, benchmark saturation — and those solutions adapt to LLM contexts.

Raters, Ratings & Human Judgment

Modeling rater effects with the hierarchical rater model (HRM) framework and its extensions. Human judgments — scoring student essays or labeling AI outputs — are measurements subject to systematic error, and psychometric rater models improve the reliability of conclusions drawn from them.

Scoring with Humans & Machines

Methods for evaluating automated scoring engines, including fairness testing, agreement metrics (and the limitations of quadratic weighted kappa), and validity arguments for constructed-response scoring with generative AI.

Scale Development & Validation

Developing and validating psychometric instruments, from social-emotional learning assessments to new scales for measuring AI behavior, including sycophancy and user metacognition.

Full list of publications on Google Scholar ↗

Contact

Get in touch

For research collaborations, consulting inquiries, or speaking engagements, reach me through LinkedIn or BroadMetrics.